# Submission format-- CSV or notebook?
**URL:** https://forum.crunchdao.com/t/submission-format-csv-or-notebook/575
**Category:** (ended) Broad Institute Crunch #1
**Created:** [November 2, 2024, 3:05am UTC](https://forum.crunchdao.com/t/submission-format-csv-or-notebook/575 "2024-11-02T03:05:22Z")
**Posts on this page:** 10
**Page:** 1
### Author:  [@dizzy-rachel](https://forum.crunchdao.com/u/dizzy-rachel)
#### Post date: [November 2, 2024, 3:05am UTC](https://forum.crunchdao.com/t/submission-format-csv-or-notebook/575/1 "2024-11-02T03:05:22Z")
For the Broad Autoimmune competition, are the submissions expected to be in the format of a CSV or as a model in a notebook? Some of the documentation says CSV (such as on this page: [Broad Institute Autoimmune Disease | CrunchDAO Docs V3](https://docs.crunchdao.com/competitions/competitions/broad-institute-autoimmune-disease)), but the dummy submission is a notebook with train and infer methods ([Submit a Notebook - Broad Institute Autoimmune Disease Competition - CrunchDAO](https://hub.crunchdao.com/competitions/broad-1/submit/via/notebook)) .
---
### Author:  [@combative-lusheng](https://forum.crunchdao.com/u/combative-lusheng)
#### Post date: [November 2, 2024, 5:22pm UTC](https://forum.crunchdao.com/t/submission-format-csv-or-notebook/575/2 "2024-11-02T17:22:06Z")
I also want to ask how to use the random-submission.ipynb. If the host would like to show demo case will be very helpful.
---
### Author:  [@cruncher-abde](https://forum.crunchdao.com/u/cruncher-abde)
#### Post date: [November 5, 2024, 4:42pm UTC](https://forum.crunchdao.com/t/submission-format-csv-or-notebook/575/3 "2024-11-05T16:42:17Z")
Hello,
We have corrected the discrepancy in the document and the notebook; the correct expected format is the one provided by the notebook. Sorry for the confusion
---
### Author:  [@spicy-questo](https://forum.crunchdao.com/u/spicy-questo)
#### Post date: [November 24, 2024, 5:56pm UTC](https://forum.crunchdao.com/t/submission-format-csv-or-notebook/575/4 "2024-11-24T17:56:37Z")
Having pipeline, which is crops and featurize images , all in all from 8 zarr standard datasets it delivers ~60gb+ , how much capacity we have in cloud, is it going to handle such size?
---
### Author:  [@spicy-questo](https://forum.crunchdao.com/u/spicy-questo)
#### Post date: [November 25, 2024, 5:52am UTC](https://forum.crunchdao.com/t/submission-format-csv-or-notebook/575/5 "2024-11-25T05:52:13Z")
alright,if we need only predict on validation and test, the train data might be cut out, that way we can avoid to allocation of excessive space in cloud.
---
### Author:  [@enzo](https://forum.crunchdao.com/u/enzo)
#### Post date: [November 25, 2024, 10:36am UTC](https://forum.crunchdao.com/t/submission-format-csv-or-notebook/575/6 "2024-11-25T10:36:09Z")
The large dataset is not available in the Runner.
You can read about resource limitations in the documentation: [Resources Limit | CrunchDAO Docs V3](https://docs.crunchdao.com/competitions/resources-limit#runs)
---
### Author:  [@spicy-questo](https://forum.crunchdao.com/u/spicy-questo)
#### Post date: [November 25, 2024, 11:22am UTC](https://forum.crunchdao.com/t/submission-format-csv-or-notebook/575/7 "2024-11-25T11:22:41Z")
i currently use Standard Dataset only, because the large dataset is excessive to my model
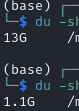
i checked the sizes of folders:
the 1.1 gb is the size of initial DC1.zarr
13 gb is the size of postprocessed DC1.zarr images where is most share is belong to centroid cropped images and additional features.
I’m gonna try to reduce it by throwing out the train data and leaving only the validation and test
---
### Author:  [@enzo](https://forum.crunchdao.com/u/enzo)
#### Post date: [November 25, 2024, 11:40am UTC](https://forum.crunchdao.com/t/submission-format-csv-or-notebook/575/8 "2024-11-25T11:40:39Z")
The GPU Runner has a disk size of 100GB.
If you encounter disk size problems, contact me as soon as possible and I will increase it.
But be careful as your model cannot be larger than 10gb.
---
### Author:  [@spicy-questo](https://forum.crunchdao.com/u/spicy-questo)
#### Post date: [November 28, 2024, 11:18am UTC](https://forum.crunchdao.com/t/submission-format-csv-or-notebook/575/9 "2024-11-28T11:18:33Z")
does rm command in infer() function will work?
or it need sudo, ! or % as precursor?
rm -r ‘/tmp/DC1.zarr’
!rm -r ‘/tmp/DC1.zarr’
%rm -r ‘/tmp/DC1.zarr’
---
### Author:  [@enzo](https://forum.crunchdao.com/u/enzo)
#### Post date: [November 28, 2024, 11:35am UTC](https://forum.crunchdao.com/t/submission-format-csv-or-notebook/575/10 "2024-11-28T11:35:48Z")
```python
import shutil
shutil.rmtree("/tmp/DC1.zarr")
```
or
```python
import os
os.system("rm -r '/tmp/DC1.zarr'")
```